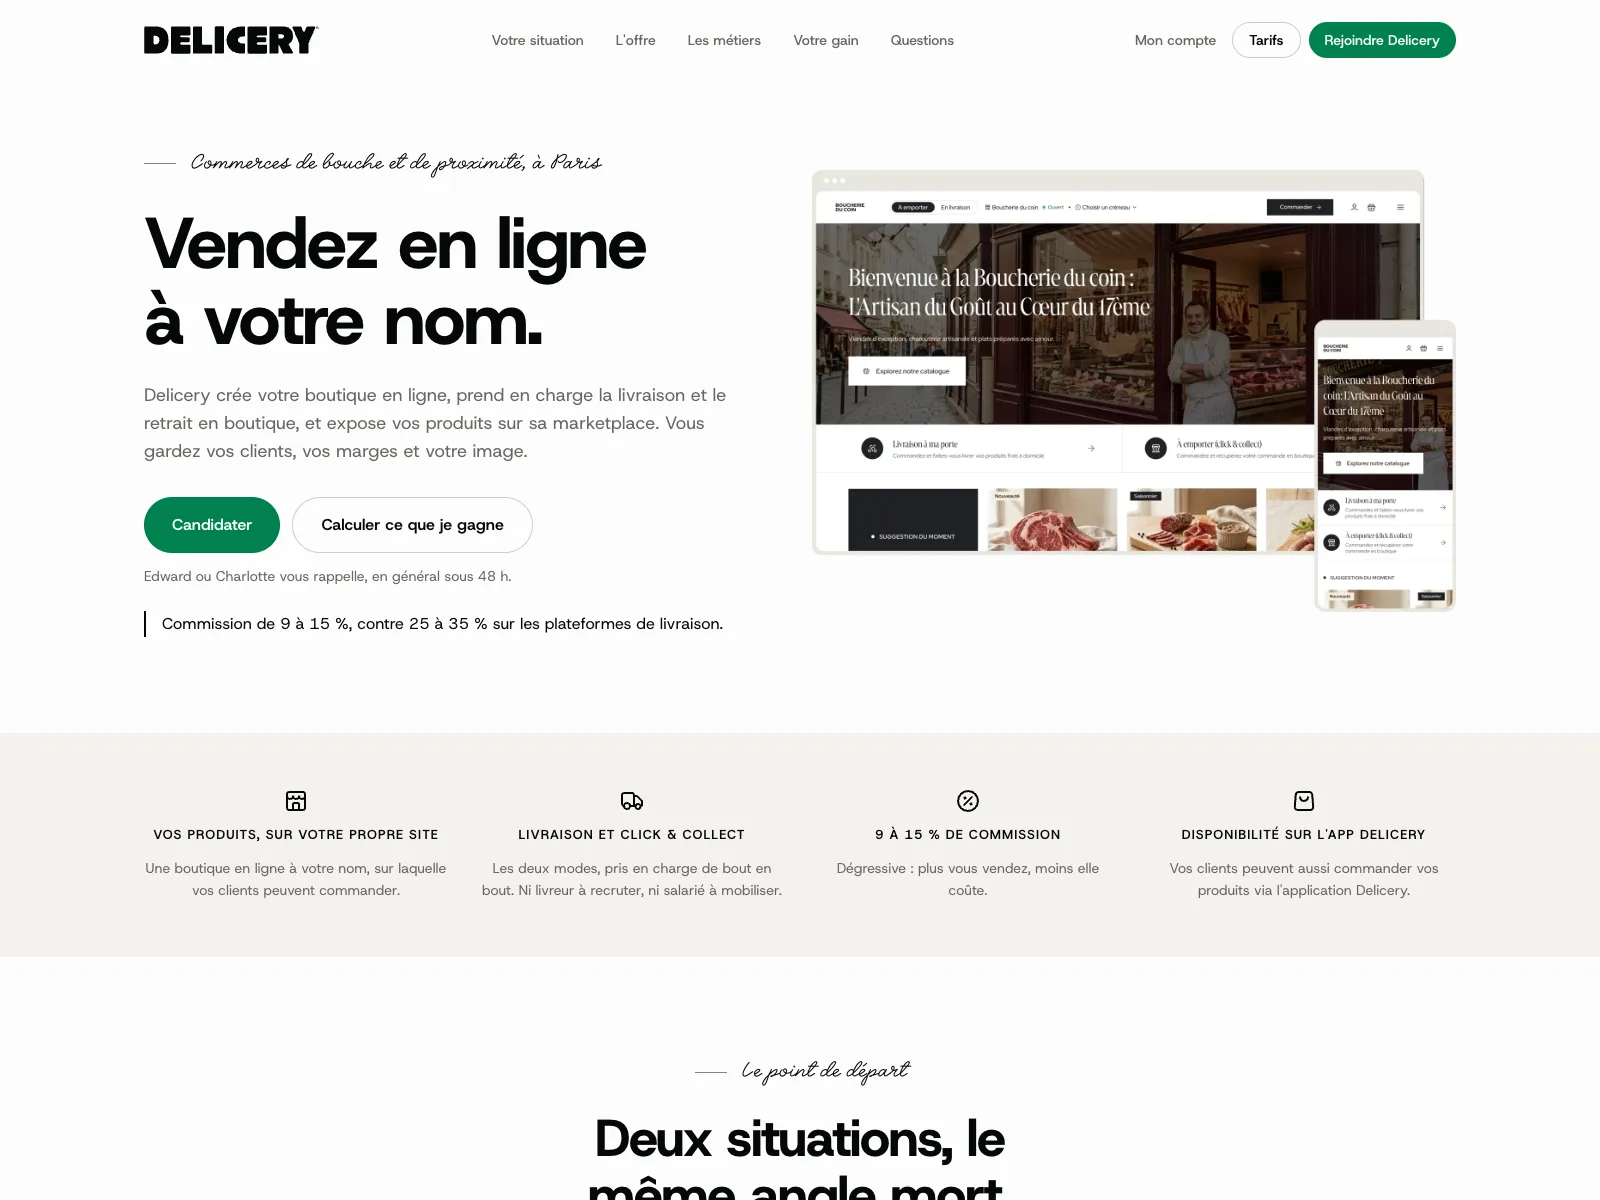
Delicery
Product, replatforming, tech lead, design, CRO, observability, agentic processes and automations for Delicery.
Logistics and mobility
Customer service, catalogue, internal operations: a pilot on one use case, measured before any rollout.
Product, replatforming, tech lead, design, CRO, observability, agentic processes and automations for Delicery.
Logistics and mobility
Since the MVP, we have worked with Replick as it builds its database for lawyers: product, funding, growth, brand and tech lead.
Legal
SaaS platform, API gateway and data models for an agentic engine that assesses legal contract quality.
Legal
UI/UX, tech lead and agentic flows of a SaaS platform for paid appointment booking.
B2B services and SaaS
An agent reads, decides and acts inside your tools. The useful cases: first-level customer service, catalogue enrichment, procedural back-office tasks, an internal copilot over your documents.
Agentic AI for Replick, agentic flows for Lawxer, agentic processes and automations for Delicery.
The evaluation set is assembled from your real cases before the agent is written, then replayed at every change of model, prompt or tool.
Guardrails live in the code, not in the prompt: explicitly allowed actions, bounded amounts and scopes, human approval on anything that commits the company, a log of tool calls and approvals.
A group-wide rollout follows a pilot measured on your data. Actions that commit money or the customer relationship go through human approval.
If the use case does not hold up in evaluation, we stop.
Technologies
No. Providers are chosen on terms that exclude training on your data; data that must not leave your perimeter goes through a model hosted on your side, or through no model at all.
Every processor, model provider included, is named with its processing region. European Union where the provider offers it; otherwise, you decide with your DPO.
The studio team. At handover, your team receives the evaluation set, the dashboard and the documentation to evolve the agent without us, or a business-hours operations contract.
Yes: a written withdrawal procedure, a measured pilot before any wide rollout, stop criteria decided with you.
Three stages, each priced separately: discovery with an evaluation set, a pilot on one use case, rollout if the evaluation holds. The price depends on the number of tools to connect, the permitted actions, the human approval to organise and the data-residency requirements.
01
Shopify Plus, headless, custom apps, ERP and logistics integrations, migrations. Commerce is what our clients entrust us with most.
03
Next.js and React platforms, portals, internal tools, audits and rescue of projects in trouble.
We reply within the week.